Data leakage in machine learning: why an impressive validation score can be completely wrong
Learn how preprocessing, time, identities, duplicates, and target information leak across a split—and how pipelines prevent it.
Reviewed September 30, 2026. Code examples use scikit-learn's public Pipeline interface; check the documentation for the installed version.
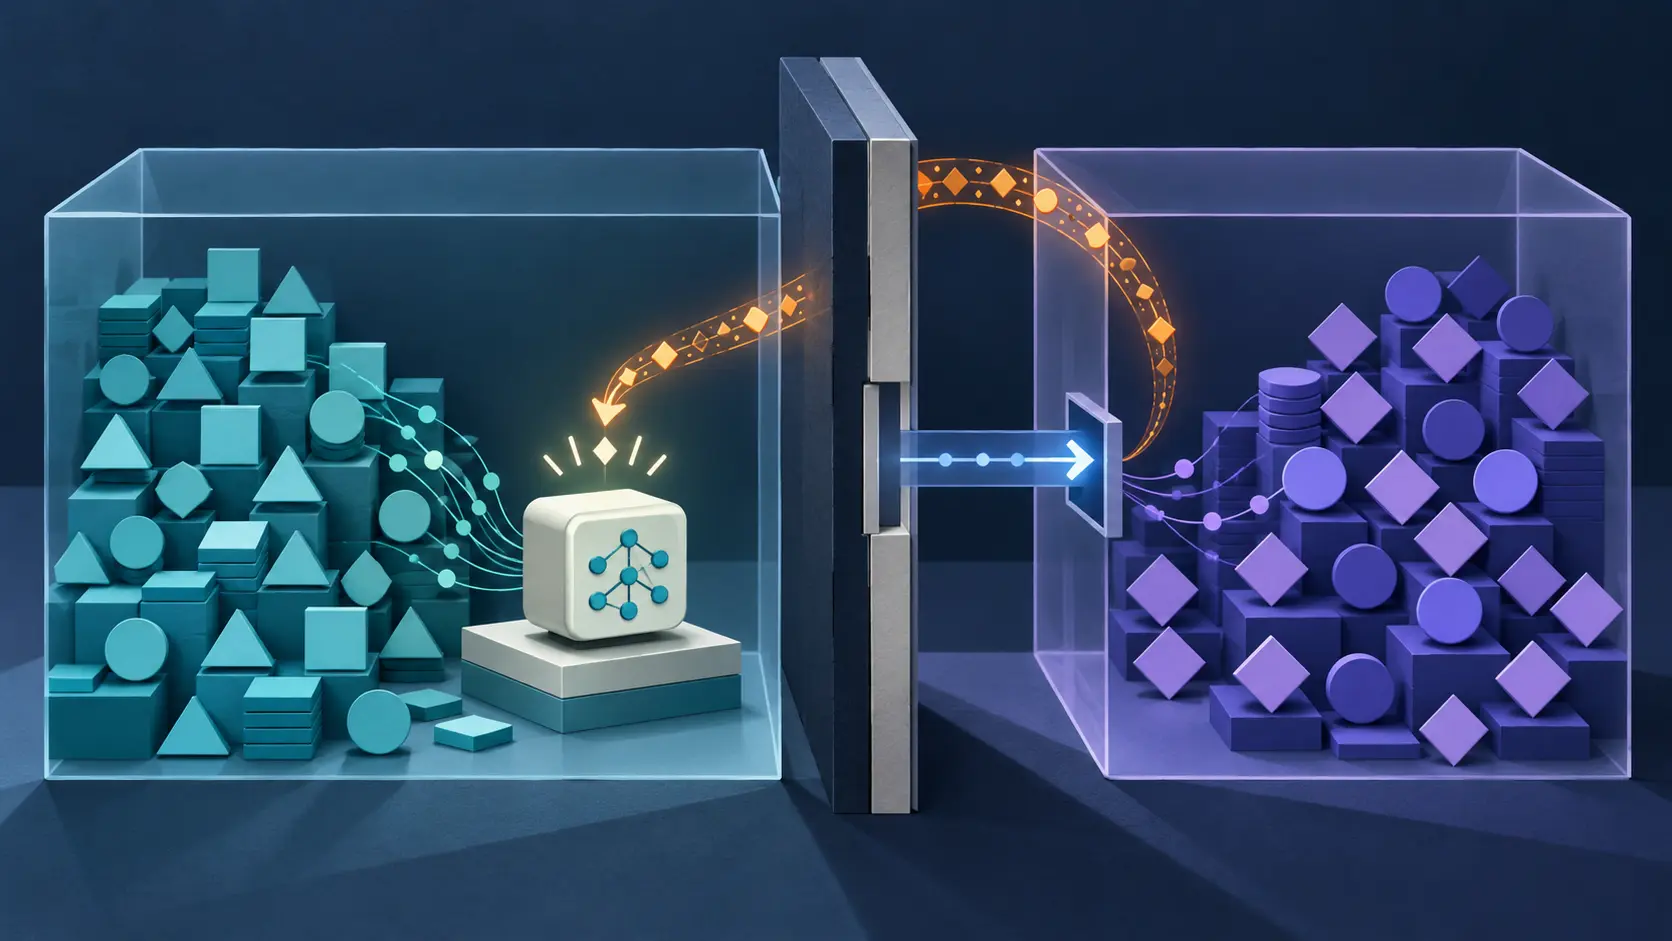
A model reaches 96% accuracy during development and collapses after deployment. One possible cause is not a weak algorithm but an invalid test: information from the future, the label, or the test set entered the training process.
Scikit-learn defines data leakage as using information during model building that would not be available at prediction time. The result is an overly optimistic estimate of performance on new data.
The boundary is the prediction moment
Ask a precise question: what information exists at the moment this prediction must be made? A feature may exist in the final database but not at prediction time. Hospital discharge status cannot predict risk at admission. A refund code created after a complaint cannot predict whether the complaint will occur.
Available before prediction→Training process
Fit only here→Unseen case
Simulate deployment→Score
Estimate future quality
Five common leakage patterns
| Pattern | Example | Why the score lies |
|---|---|---|
| Preprocessing leakage | Scaling or imputing on the full dataset before splitting. | Test-set statistics influence the fitted transformation. |
| Target leakage | A post-outcome field closely encodes the label. | The model sees information unavailable at prediction time. |
| Entity leakage | Records from the same patient appear in train and test. | The model partly recognizes the person rather than generalizing. |
| Temporal leakage | A random split lets future records train a model evaluated on the past. | The experiment violates the direction of deployment time. |
| Duplicate leakage | Near-identical rows or augmented copies cross folds. | The test contains examples the model has effectively seen. |
Wrong order: preprocess, then split
Suppose missing values are filled using the median and numeric columns are standardized. If those steps are fitted on all rows, the validation rows help determine the median and mean used to transform training data.
# Incorrect: the transformer sees the future test rows
X_scaled = scaler.fit_transform(X)
X_train, X_test, y_train, y_test = train_test_split(
    X_scaled, y, test_size=0.2, random_state=42
)
The leak may be small in one dataset and severe in another. The rule stays the same: split first, then fit every learned transformation only on the training subset.
Correct order: put transformations in a pipeline
from sklearn.compose import ColumnTransformer
from sklearn.impute import SimpleImputer
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import OneHotEncoder, StandardScaler

X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, random_state=42, stratify=y
)

numeric = make_pipeline(SimpleImputer(strategy="median"), StandardScaler())
categorical = make_pipeline(
    SimpleImputer(strategy="most_frequent"),
    OneHotEncoder(handle_unknown="ignore")
)

preprocess = ColumnTransformer([
    ("num", numeric, numeric_columns),
    ("cat", categorical, categorical_columns),
])

model = make_pipeline(preprocess, LogisticRegression(max_iter=1000))
model.fit(X_train, y_train)
score = model.score(X_test, y_test)
During cross-validation, scikit-learn clones and fits the pipeline inside each training fold. The validation fold receives only transform and predict. Feature selection, PCA, imputation, encoding, and scaling all belong inside that fold-aware pipeline.
Target leakage hides in plausible columns
Column names rarely announce “I contain the answer.” Investigate how each feature is created and when it becomes available.
- For default prediction, a collection-status field may be written only after default.
- For disease prediction, a treatment code may be assigned after diagnosis.
- For churn prediction, an account-closure reason is a consequence of churn.
- For fraud detection, a manual-review outcome may include knowledge from the investigation.
A correlation table cannot solve this alone. You need a data lineage conversation with the people who produce and use the field.
Choose the split that matches deployment
| Deployment question | Split strategy | Keep together or ordered |
|---|---|---|
| Predict new independent rows from the same process | Random or stratified split. | Preserve class proportion when appropriate. |
| Predict for a new patient, store, user, or machine | Group-aware split. | All rows from one entity stay in one fold. |
| Predict future events | Time-ordered or rolling split. | Training times precede validation times. |
| Generalize to a new location or institution | Group by site. | Entire hospitals, schools, or branches stay together. |
GroupKFold and related group splitters help keep entities separate. TimeSeriesSplit creates expanding time-ordered folds. They are tools, not automatic guarantees: your group identifier and timestamp must match the real independence boundary.
Hyperparameter tuning can leak too
If you repeatedly check the test set and choose the model that performs best on it, the test set becomes part of model selection. Use training folds for tuning and reserve a final holdout for one unbiased estimate. For small datasets, nested cross-validation can separate inner tuning from outer evaluation.
A test set is a scarce resource. Each decision based on its score transfers information from the test set into the development process.
Leakage checks before trusting a score
- Write the exact prediction time and list which fields exist then.
- Trace every feature to its source, creation time, and update rule.
- Search for identifiers, duplicates, post-outcome fields, and suspiciously predictive single columns.
- Place all learned preprocessing inside the cross-validation pipeline.
- Group or order the split to mirror future use.
- Fit the pipeline only on training folds; transform validation and test folds.
- Keep a final holdout untouched until the design is fixed.
- Compare performance after removing suspicious features or stricter grouping.
Diagnosing a suspiciously good result
Unexpectedly high performance is not proof of leakage, but it is a reason to investigate. Train a simple baseline, inspect per-feature importance, remove post-event fields, deduplicate before splitting, and evaluate on a later time window or a new group. If the score falls sharply under the deployment-like split, the stricter number is usually the more useful estimate.
The goal is not the highest validation score. It is an honest forecast of how the model behaves when the answer is no longer available through a shortcut.