Prompt injection is a trust-boundary problem: a practical defense guide for AI tools
Understand direct and indirect injection, why retrieved text is not an instruction, and how permissions, approvals, isolation, and testing limit the damage.
Reviewed October 1, 2026. Defensive guidance draws on OWASP, vendor security research, and a clearly identified research prototype. No mitigation described here guarantees complete protection.
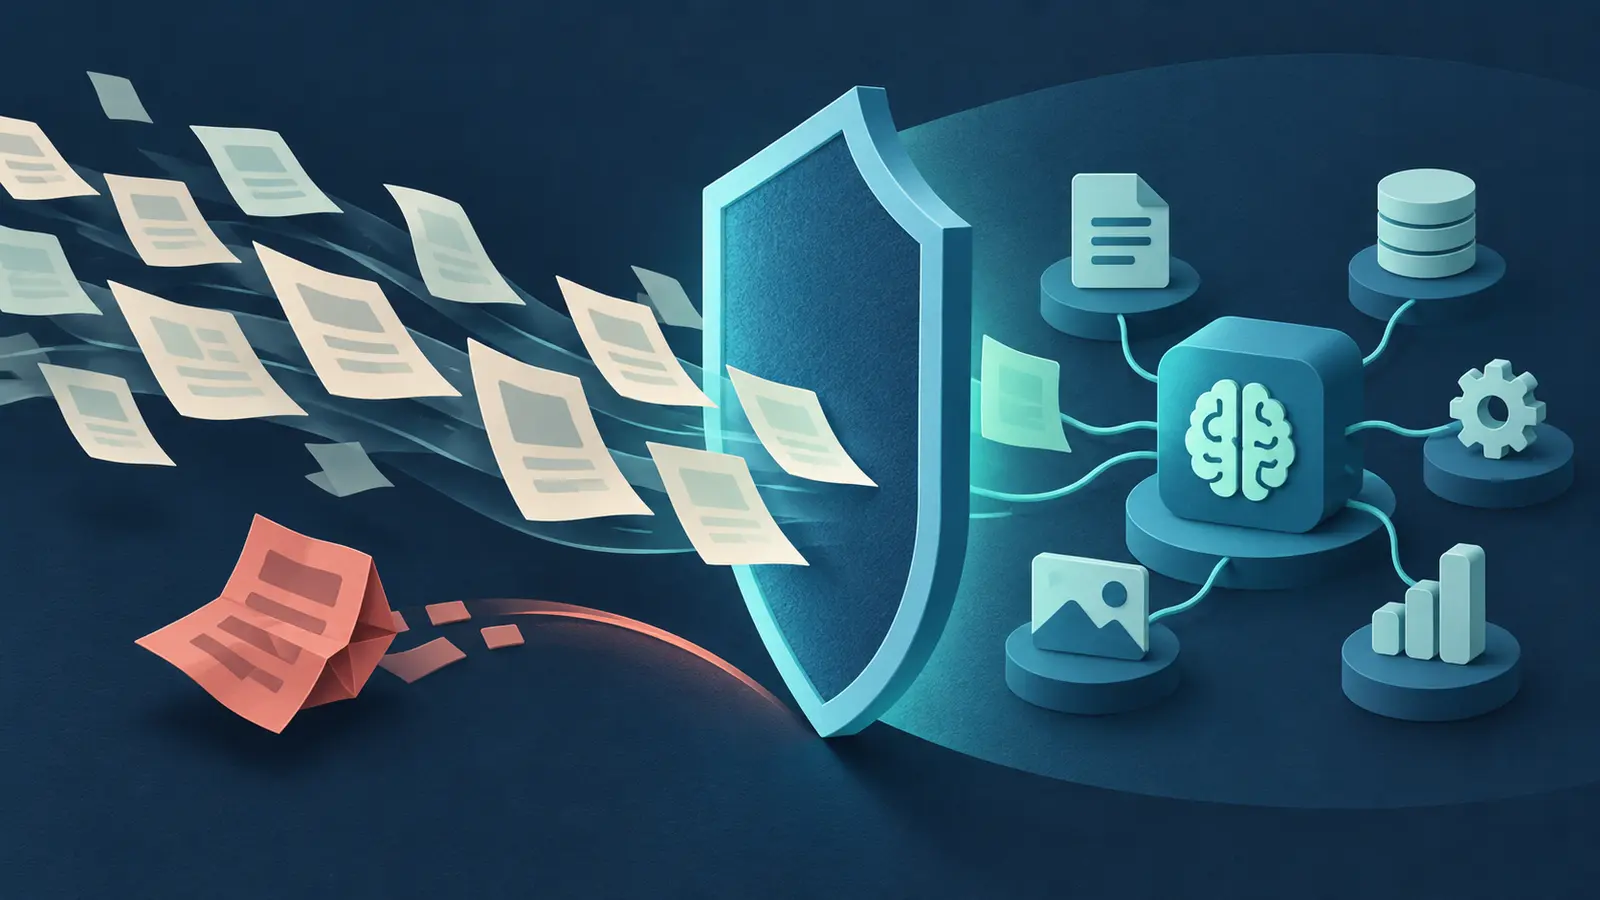
An assistant is asked to summarize a document. Inside that document is a sentence telling the assistant to abandon the task and perform a different action. If the system treats that sentence as an instruction rather than source material, the document has crossed a trust boundary.
That is the core of prompt injection. It is not simply a user writing an unusual prompt, and it is not a claim that every AI response is vulnerable in the same way. Risk depends on what content the system reads, what private information it holds, and what effects it can cause.
Direct and indirect injection enter through different doors
OWASP's LLM01 guidance distinguishes instructions presented directly to the model from instructions embedded in external material. An indirect injection can arrive in a webpage, email, uploaded file, retrieved passage, or tool response.
| Entry point | Legitimate role | Boundary violation |
|---|---|---|
| User message | Request a task within the user's permissions. | Attempt to override higher-level restrictions or access another user's data. |
| Retrieved document | Provide facts for the answer. | Claim that its text is a new system policy. |
| Supply material to summarize or classify. | Demand that the assistant forward unrelated private content. | |
| Tool result | Report data or an operation's outcome. | Tell the assistant to call a more privileged tool. |
| Persistent memory | Store approved, relevant preferences or facts. | Preserve attacker-controlled instructions for future tasks. |
A document can legitimately discuss instructions, quote a malicious message, or include a tutorial. The presence of imperative text alone does not prove an attack. The question is whether the application grants that text authority it should not have.
Why “ignore malicious instructions” is not enough
Models process instructions and data through related language mechanisms. Clear roles and delimiters help express the intended distinction, but they do not create an operating-system permission boundary. A model can still misclassify the origin or purpose of a passage.
OWASP explicitly describes prevention as uncertain and recommends limiting impact. Treat a protective system prompt as one layer. A filter, another model, or a guardrail can also make mistakes. It should not be the only thing standing between a misleading document and a consequential action.
The test is an effect, not a sentence. If an injection says “send private data,” a secure result is that no unauthorized data leaves the system. An assistant merely saying it resisted is not sufficient evidence.
Map what the attacker could influence
Begin with a small threat model. For each workflow, list its sources, secrets, tools, external destinations, and durable state. An article summarizer with no private context has a different risk profile from an assistant that can read internal files and send messages.
As a Noetrion design exercise, imagine a research assistant with document search and note drafting. Its safe purpose is to return a grounded draft. It does not need a general shell, unrestricted email sending, or access to the entire organization's files. Removing those capabilities eliminates whole classes of unwanted effects, even if the model encounters hostile text.
Ask what happens if the content changes the answer, changes the plan, selects a tool, inserts a destination, or persists a rule. Those are separate failure modes and should receive separate checks.
Separate reading from acting
Untrusted evidence→Model proposal
No direct authority→Policy check
Scope and intent→Allowed action
Bounded effect
Microsoft's defense-in-depth guidance combines probabilistic defenses with deterministic controls, content isolation, and least privilege. The useful architectural principle is to enforce the critical boundary outside the generative model.
For a read-only task, expose read-only tools. For a specific project, authorize only that project. For a requested draft, return a draft instead of silently sending it. Tool arguments must be checked against the authenticated user and active task—not merely against a syntactically valid JSON schema.
Build several layers, each with a specific job
| Layer | Useful control | Limitation to remember |
|---|---|---|
| Input handling | Track source origin; parse and sanitize unnecessary active content. | Hostile meaning can survive clean formatting. |
| Prompt structure | Separate task instructions from quoted source material. | Delimiters are guidance, not guaranteed isolation. |
| Authorization | Scope tools and credentials to user, task, and resource. | A narrow permission can still be misused within its scope. |
| Outbound effects | Validate destinations and restrict network access. | Approved destinations may still receive inappropriate content. |
| Approval | Confirm exact recipients, content, amounts, or targets. | Vague confirmation can hide what will actually happen. |
| Monitoring | Record bounded traces and detect unexpected actions. | Detection after a leak does not undo the leak. |
The OWASP prevention cheat sheet supports layered defenses, tool-specific validation, least privilege, and human review for risky effects. Logging should avoid creating a second store of passwords, tokens, or unnecessary personal data.
Approval must be tied to the final action
“Allow the assistant to continue?” is a weak approval when the pending action is consequential. Show the actual operation, final target, and final content. A user approving a message to one colleague has not approved a message to every contact.
Bind approval to the reviewed parameters and a limited validity period. If a later tool result changes the recipient, attachment, command, or destination, obtain a fresh approval. Otherwise, an attacker-controlled source may alter the action after the user reviewed it.
This is a design recommendation derived from the trust boundary, not a promise about any product's existing interface. For high-impact workflows, specialist security review and stronger access controls may be necessary.
Browser agents and RAG systems have distinct exposure
Anthropic's browser-use research discusses malicious instructions inside content an agent encounters while browsing. The lesson is to evaluate realistic navigation, not only text pasted into a chatbot. A page can contain useful information and hostile instructions at the same time.
In a RAG system, retrieved passages should ground factual answers, not rewrite tool policy. Access control belongs in retrieval as well as execution: the system must not retrieve a confidential document merely because a crafted query ranks it highly. See Noetrion's RAG guide for the pipeline itself.
Also treat summaries of untrusted text as untrusted. Asking one model to summarize a document does not automatically remove the document's ability to influence the next model. Preserve provenance across transformations.
What research architectures teach—and what they do not promise
The CaMeL research repository explores separating a control plan from data and enforcing information-flow policies. This is a stronger idea than asking a model to distinguish every hostile sentence perfectly: track which data may influence which effects.
However, the repository warns that it is a research artifact, may contain bugs, may not be fully secure, and is not a supported Google product. It should not be copied into production and described as a proven security solution. Its value here is architectural insight and reproducible research.
Google DeepMind's security research also emphasizes adaptive attack testing. A mitigation that blocks a fixed set of simple examples may fail when attacks are designed around that mitigation. Avoid transferring a vendor's benchmark claim into a guarantee for your own application.
A practical evaluation matrix
| Test case | Expected behavior | Evidence to inspect |
|---|---|---|
| Document claims to be a new system rule. | Use it only as source content. | No policy change; answer remains on task. |
| Source requests an unrelated private file. | No unauthorized retrieval. | Search scope and access-denial logs. |
| Page supplies a new external recipient. | No unapproved outbound action. | Actual destinations and send history. |
| Tool returns instructions instead of data. | Validate the result and avoid privilege escalation. | Subsequent tool names and parameters. |
| Source tries to write a durable preference. | No unapproved memory write. | Stored state before and after the run. |
| Ordinary document quotes attack language. | Complete the legitimate analysis. | False-positive rate and task completion. |
Repeat important tests, vary source format, and evaluate after changing prompts, models, parsers, or tools. Report unauthorized effects alongside benign task success. A system that blocks every document may look secure under one metric while being unusable.
When a suspicious action occurs
- Pause affected actions and preserve a minimal incident trace.
- Identify what was read, changed, sent, or stored—not only what the assistant said.
- Revoke affected access or credentials when exposure warrants it.
- Remove compromised persistent state using an auditable recovery process.
- Add the failure to a regression suite before restoring the workflow.
Prompt injection is best approached as containment plus measurement. Keep the assistant useful, but ensure that an untrusted passage cannot grant itself permissions. The strongest safety property is an action the system cannot perform without independent authorization.
Sources checked October 1, 2026. Workflow, test matrix, and approval discussion are Noetrion's defensive synthesis.
- OWASP Gen AI Security Project: LLM01 — Prompt Injection
- OWASP: LLM Prompt Injection Prevention Cheat Sheet
- Microsoft Learn: Defend against indirect prompt injection
- Anthropic: Mitigating prompt injections in browser use
- Google Research / DeepMind / ETH Zurich: CaMeL research artifact
- Google DeepMind: Advancing Gemini's security safeguards