CSV vs Parquet: choose a data format by workload, not by file extension
Understand row-oriented text, columnar storage, schemas, compression, pushdown, and a safe conversion workflow in Python and SQL.
Reviewed September 30, 2026. Performance depends on the engine, compression, row-group layout, storage, and query. Treat the qualitative comparisons below as design guidance, not a universal benchmark.
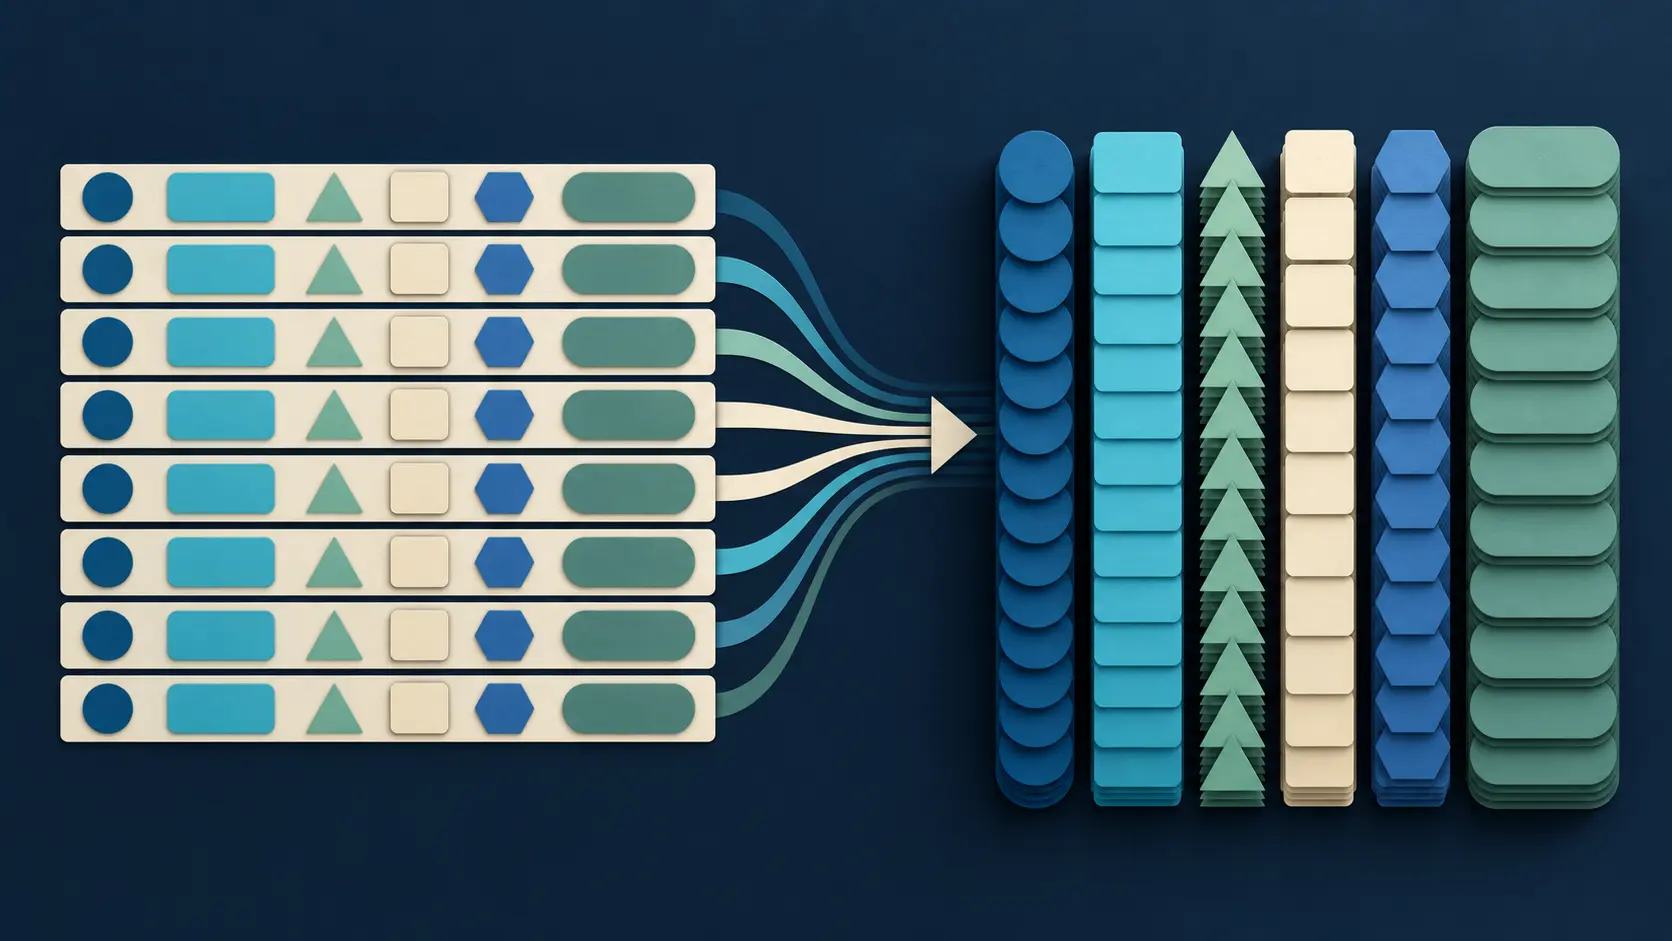
CSV is easy to open, inspect, generate, and exchange. Parquet is designed for efficient analytical storage and retrieval. Neither format is “better” in every situation; they optimize different work.
What a CSV file actually stores
CSV is delimited text. A header may name the fields, but the file does not provide a universal type system. The bytes 00123, 2026-09-30, and an empty field require interpretation by the reader.
order_id,date,city,total
00123,2026-09-30,Surabaya,125000
00124,2026-09-30,Jakarta,99000
This simplicity is a strength for exchange and debugging. It also moves work to the parser: delimiters, quotes, encodings, missing values, decimals, dates, and leading zeroes must be handled consistently.
How Parquet organizes the same table
Apache Parquet is a column-oriented file format. A file contains one or more row groups. Each row group contains one contiguous column chunk per column, and column chunks are divided into pages. Encoding and compression operate at the page level.
- Header text
- Row 1: every field
- Row 2: every field
- Row 3: every field
- Row group
- order_id column chunk
- date column chunk
- city and total chunks
Because values in one column usually share a type and often repeat patterns, column-oriented encoding and compression can be effective. The file also carries schema and metadata that engines use to navigate the data.
The practical differences
| Concern | CSV | Parquet |
|---|---|---|
| Human inspection | Excellent. Open in a text editor. | Needs a compatible reader. |
| Schema and types | Reader infers or receives rules separately. | Stored in the file. |
| Compression | Usually whole-file external compression. | Column-aware encoding and compression. |
| Select a few columns | Parser generally reads each row. | Projection can read only required columns. |
| Skip filtered regions | Limited without an external index. | Statistics may allow row-group or page skipping. |
| Streaming append | Simple to append text rows carefully. | Usually written in batches; layout choices matter. |
| Interchange | Nearly universal. | Strong across analytical tools, less universal elsewhere. |
Projection and filter pushdown
Suppose a dataset contains 80 columns, but a query only needs date, city, and total. DuckDB's Parquet reader can push the projection into the scan and read only those columns. A filter such as date >= DATE '2026-09-01' can also be pushed down; metadata may let the engine skip row groups whose ranges cannot match.
SELECT city, SUM(total) AS revenue
FROM 'orders.parquet'
WHERE date >= DATE '2026-09-01'
GROUP BY city
ORDER BY revenue DESC;
Skipping is not guaranteed to be equally effective for every file. Row-group size, sort order, statistics, compression, and data distribution all affect the result. A badly organized Parquet dataset can underperform a well-designed one.
When CSV is the right choice
- A person must inspect or edit a small extract without specialized software.
- A public download needs the broadest compatibility.
- A system emits simple line-oriented records and another step immediately ingests them.
- The file is small enough that parse cost and storage are not meaningful constraints.
- You need a transparent handoff artifact beside a formal data dictionary.
CSV remains valuable because failures are visible. If a delimiter or quote is broken, you can often open the file and see why.
When Parquet earns its complexity
- Analysts repeatedly scan large tables.
- Queries use subsets of columns.
- Storage and transfer costs matter.
- Preserving numeric, boolean, date, timestamp, nested, or null types matters.
- Files feed engines such as DuckDB, Spark, Polars, pandas, or a data lake.
Parquet is a file format, not a database. It does not provide transactions, concurrent updates, constraints, access control, or record-level mutation by itself. If many users edit operational state, use a database and export Parquet for analytics.
Convert with an explicit schema check
import pandas as pd

df = pd.read_csv(
    "orders.csv",
    dtype={"order_id": "string", "city": "string"},
    parse_dates=["date"]
)

assert df["order_id"].notna().all()
assert (df["total"] >= 0).all()

df.to_parquet(
    "orders.parquet",
    index=False,
    compression="zstd"
)

check = pd.read_parquet("orders.parquet")
assert len(check) == len(df)
assert list(check.columns) == list(df.columns)
Explicitly protect identifiers with leading zeroes, parse dates intentionally, validate ranges and nulls, and compare row counts. A conversion can succeed technically while changing meaning.
Partitioning is not a substitute for thinking
A Parquet dataset is often split into directories such as year=2026/month=09/. Partitioning can help an engine skip files, but too many tiny files create metadata and scheduling overhead. Choose partition columns that appear in common filters and have manageable cardinality.
| Layout symptom | Likely problem | Direction to test |
|---|---|---|
| Thousands of tiny files | Too much partitioning or overly frequent writes. | Compact into fewer, larger files. |
| Selective query scans most row groups | Loose min/max ranges. | Sort by commonly filtered columns before writing. |
| One file cannot use available parallelism | Row groups are too large or too few. | Test row-group sizing for the target engine. |
| Schema differs across files | Uncontrolled evolution. | Validate schemas and define compatibility rules. |
A defensible workflow
Keep the raw source→Validate
Types, nulls, keys→Convert
Write controlled Parquet→Verify
Counts and sample queries
- Store the original CSV immutably with its source date and checksum.
- Define expected columns and types instead of relying entirely on inference.
- Reject or quarantine malformed rows; do not silently drop them.
- Write Parquet with a compression and row-group strategy suited to the workload.
- Verify schema, row count, null count, numeric totals, and representative queries.
- Version the conversion code and record the library versions used.
Choose CSV for transparency and interchange. Choose Parquet for typed, repeated analytical scans. In many pipelines the correct answer is both: preserve the raw CSV, then produce a validated Parquet layer for analysis.